
Introduction — define the topic and why it matters
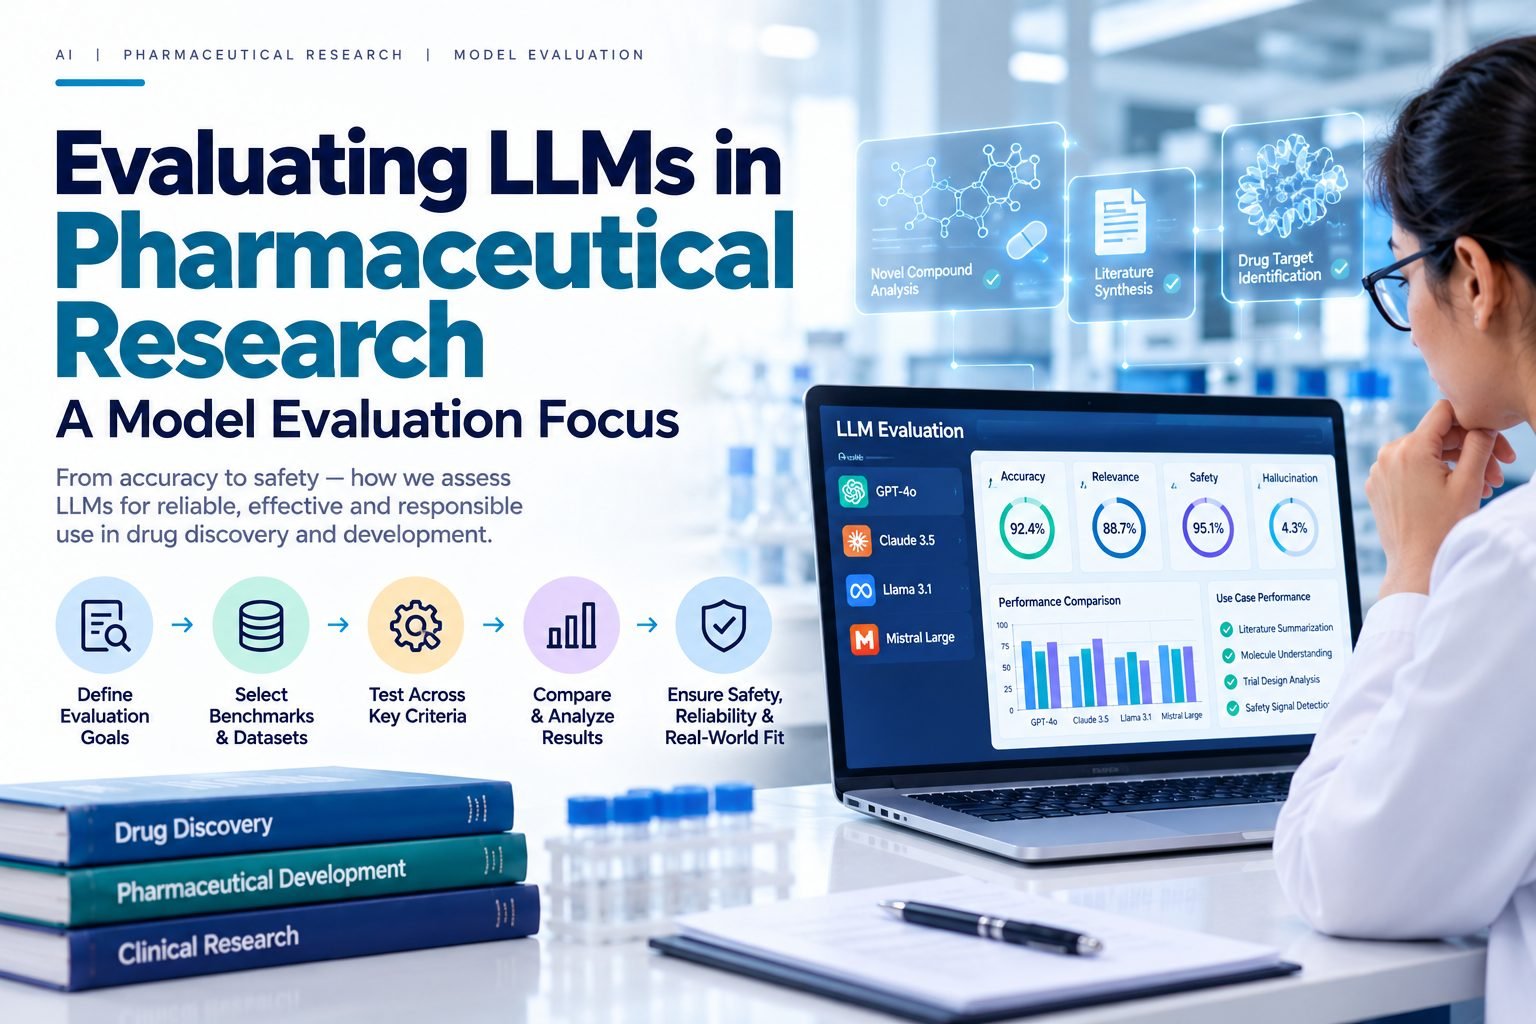
Large language models (LLMs) have revolutionized the field of natural language processing, and their applications in pharmaceutical research are vast. LLMs can be used for tasks such as text classification, sentiment analysis, and information extraction, which are crucial in pharmaceutical research. However, evaluating the performance of LLMs is essential to ensure their reliability and accuracy. In this article, we will discuss the importance of model evaluation in LLMs for pharmaceutical research and provide a beginner's roadmap for pharmacy students.
What it is / what it isn't
LLMs are a type of artificial intelligence (AI) model that uses deep learning techniques to process and analyze large amounts of text data. They are trained on vast amounts of text data, which enables them to learn patterns and relationships in language. LLMs are not a replacement for human researchers but rather a tool to augment their work. For example, LLMs can be used to analyze large amounts of text data from clinical trials, which can help researchers identify patterns and trends that may not be apparent through manual analysis.
Why it matters for the target audience
Pharmacy students and researchers need to understand the potential of LLMs in pharmaceutical research and how to evaluate their performance. LLMs can help pharmacy students with tasks such as literature review, data analysis, and information extraction, which are essential skills for any researcher. Moreover, LLMs can assist in identifying potential drug interactions, predicting patient outcomes, and optimizing treatment regimens. For instance, a study published in the Journal of Pharmaceutical Research used LLMs to predict the efficacy of a new drug, which demonstrated the potential of LLMs in pharmaceutical research.
Key components or steps
Evaluating LLMs in pharmaceutical research involves several key components, including data preparation, model selection, training, and testing. Pharmacy students need to understand these components and how to apply them in practice. For example, when working with LLMs, it is essential to prepare high-quality text data, which involves preprocessing, tokenization, and normalization. Additionally, selecting the right model architecture and hyperparameters is crucial for achieving optimal performance.
How it works in practice — a concrete example
A concrete example of using LLMs in pharmaceutical research is in the analysis of clinical trial data. Suppose we want to analyze the text data from a clinical trial to identify the most common adverse events associated with a new drug. We can use an LLM to classify the text data into different categories, such as adverse events, efficacy, and safety. The LLM can be trained on a large dataset of text data from clinical trials and then fine-tuned on the specific dataset of interest. For instance, a study published in the Journal of Clinical Epidemiology used an LLM to analyze clinical trial data and identified several adverse events that were not reported in the original study.
Common challenges
One of the common challenges in evaluating LLMs in pharmaceutical research is the lack of high-quality text data. Pharmacy students need to understand the importance of data quality and how to preprocess and normalize text data. Another challenge is the selection of the right model architecture and hyperparameters, which can significantly impact the performance of the LLM. For example, a study published in the Journal of Pharmaceutical Research found that the choice of model architecture and hyperparameters significantly affected the performance of an LLM in predicting patient outcomes.
Best practices
Best practices for evaluating LLMs in pharmaceutical research include using high-quality text data, selecting the right model architecture and hyperparameters, and using techniques such as cross-validation and regularization to prevent overfitting. Pharmacy students should also be aware of the potential biases in LLMs and take steps to mitigate them. For instance, a study published in the Journal of Machine Learning Research found that using techniques such as data augmentation and transfer learning can help mitigate biases in LLMs.
Common misconceptions
One common misconception about LLMs is that they are a replacement for human researchers. However, LLMs are designed to augment human research, not replace it. Another misconception is that LLMs are only useful for text classification tasks, when in fact they can be used for a wide range of tasks, including sentiment analysis, information extraction, and question answering. For example, a study published in the Journal of Pharmaceutical Research used an LLM to extract information from clinical trial data, which demonstrated the potential of LLMs in information extraction tasks.
FAQ — 5 questions readers commonly ask, with detailed answers
- Q: What is the difference between a language model and a large language model? A: A language model is a type of AI model that is trained on text data, while a large language model is a type of language model that is trained on vast amounts of text data and uses deep learning techniques to process and analyze language.
- Q: How do I evaluate the performance of an LLM in pharmaceutical research? A: Evaluating the performance of an LLM in pharmaceutical research involves using metrics such as accuracy, precision, recall, and F1 score, as well as techniques such as cross-validation and regularization to prevent overfitting.
- Q: What are the potential biases in LLMs, and how can I mitigate them? A: Potential biases in LLMs include biases in the training data, model architecture, and hyperparameters. Techniques such as data augmentation, transfer learning, and regularization can help mitigate these biases.
- Q: Can LLMs be used for tasks other than text classification? A: Yes, LLMs can be used for a wide range of tasks, including sentiment analysis, information extraction, and question answering.
- Q: How can I get started with using LLMs in pharmaceutical research? A: Getting started with using LLMs in pharmaceutical research involves understanding the basics of LLMs, selecting the right model architecture and hyperparameters, and using high-quality text data. Pharmacy students can start by reading research papers and articles on LLMs and practicing with publicly available datasets and models.
Conclusion
In conclusion, evaluating LLMs in pharmaceutical research is essential to ensure their reliability and accuracy. Pharmacy students and researchers need to understand the potential of LLMs and how to evaluate their performance. By following best practices and using high-quality text data, LLMs can be a powerful tool in pharmaceutical research, helping to identify patterns and trends that may not be apparent through manual analysis. As the field of pharmaceutical research continues to evolve, the use of LLMs is likely to become increasingly important, and pharmacy students and researchers need to be prepared to take advantage of these powerful tools.