Introduction
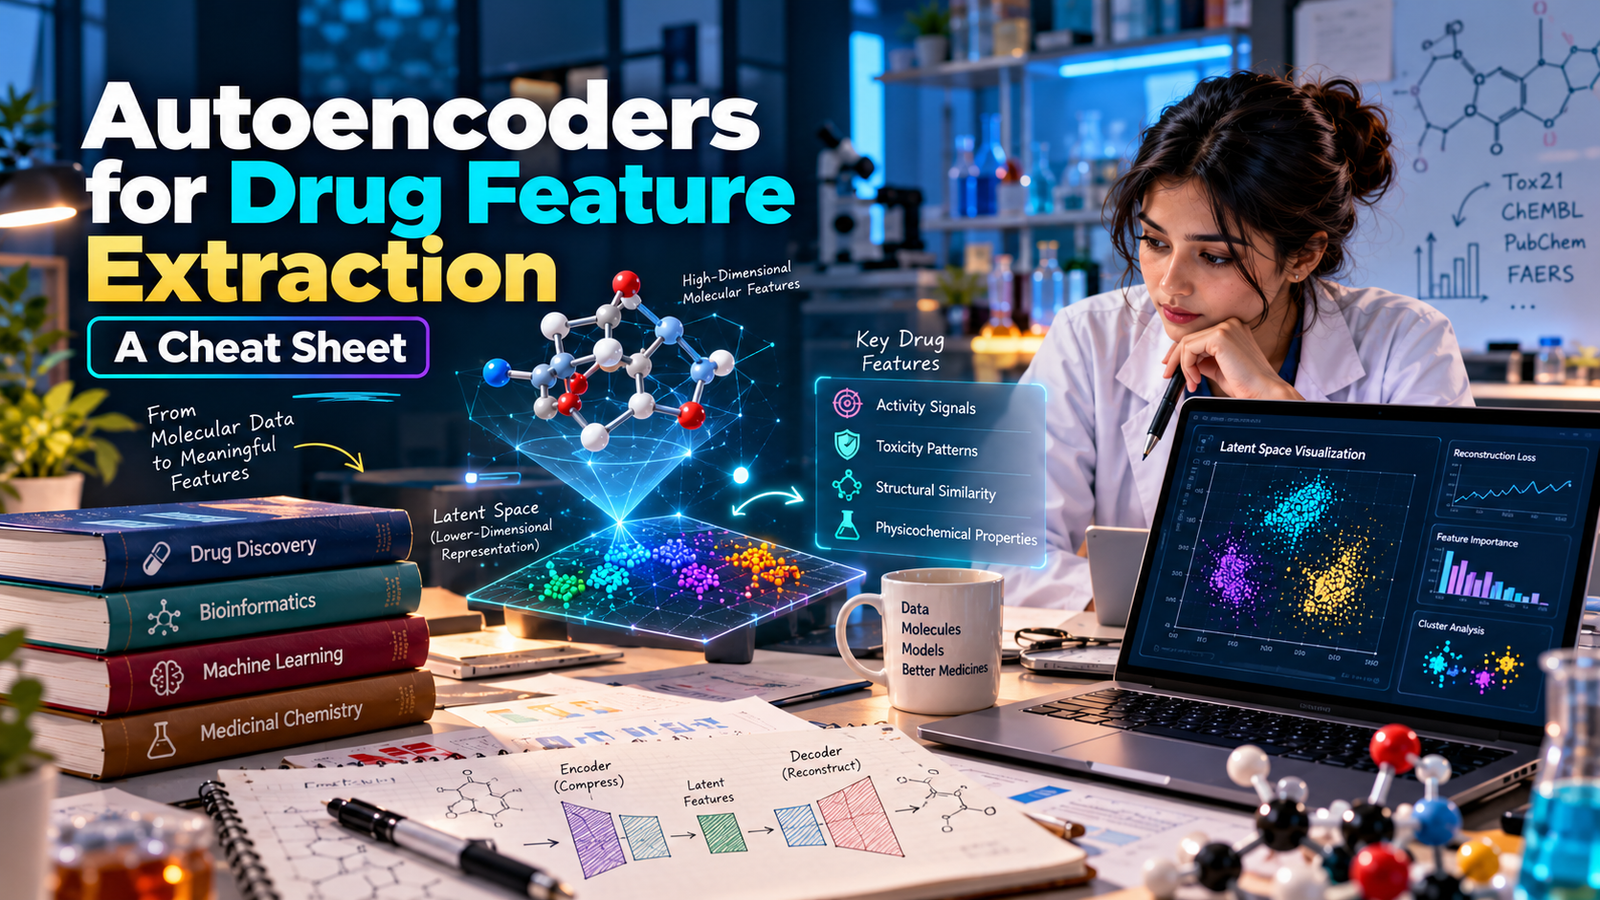
Autoencoders are a type of neural network used for dimensionality reduction and feature extraction. In the context of drug discovery and development, autoencoders can help identify key features of drugs that contribute to their efficacy and safety. This article provides a concise guide to using autoencoders for drug feature extraction, focusing on real public datasets.
For example, the Tox21 dataset, a public dataset of toxicological data, can be used to train autoencoders to extract features related to drug toxicity.
What it is / what it isn't
An autoencoder is a neural network that consists of an encoder and a decoder. The encoder maps the input to a lower-dimensional representation, while the decoder maps the lower-dimensional representation back to the original input. Autoencoders are not the same as principal component analysis (PCA), which is a linear dimensionality reduction technique.
Autoencoders can be used for feature extraction, anomaly detection, and generative modeling. However, they are not suitable for regression tasks or classification tasks with a large number of classes.
For instance, autoencoders can be used to extract features from the ChEMBL dataset, a large collection of bioactive molecules, to identify potential lead compounds.
Why it matters for the target audience
Clinical pharmacists need to understand the properties of drugs that affect their efficacy and safety. Autoencoders can help identify these properties by extracting relevant features from large datasets. This can lead to better drug development and more effective treatment strategies.
For example, autoencoders can be used to analyze the FDA's Adverse Event Reporting System (FAERS) dataset to identify patterns of adverse events associated with specific drugs.
Key components or steps
The key components of an autoencoder are the encoder and decoder. The encoder maps the input to a lower-dimensional representation, while the decoder maps the lower-dimensional representation back to the original input. The steps involved in training an autoencoder include data preprocessing, model selection, and hyperparameter tuning.
The following table summarizes the key components and steps:
| Component/Step | Description |
|---|---|
| Encoder | Maps input to lower-dimensional representation |
| Decoder | Maps lower-dimensional representation back to original input |
| Data preprocessing | Normalizing and transforming data for training |
| Model selection | Choosing the type of autoencoder (e.g., convolutional, recurrent) |
| Hyperparameter tuning | Adjusting parameters (e.g., learning rate, batch size) for optimal performance |
How it works in practice — a concrete example
Consider the example of using autoencoders to extract features from the PubChem dataset, a large collection of small molecule compounds. The goal is to identify potential lead compounds for a specific disease target. The autoencoder is trained on a subset of the dataset, and the extracted features are used to train a classification model to predict bioactivity.
The following code snippet demonstrates how to train an autoencoder using the PyTorch library:
import torch
import torch.nn as nn
import torch.optim as optim

class Autoencoder(nn.Module):
    def __init__(self):
        super(Autoencoder, self).__init__()
        self.encoder = nn.Sequential(
            nn.Linear(1024, 256),
            nn.ReLU(),
            nn.Linear(256, 128)
        )
        self.decoder = nn.Sequential(
            nn.Linear(128, 256),
            nn.ReLU(),
            nn.Linear(256, 1024)
        )

    def forward(self, x):
        x = self.encoder(x)
        x = self.decoder(x)
        return x

# Initialize the autoencoder and optimizer
autoencoder = Autoencoder()
optimizer = optim.Adam(autoencoder.parameters(), lr=.001)

# Train the autoencoder
for epoch in range(100):
    for x in dataset:
        x = autoencoder(x)
        loss = nn.MSELoss()(x, dataset)
        optimizer.zero_grad()
        loss.backward()
        optimizer.step()
Common challenges
One common challenge when using autoencoders is selecting the optimal number of layers and neurons. Another challenge is avoiding overfitting, which can occur when the autoencoder is too complex and learns the noise in the training data.
For example, using a large number of layers can lead to vanishing gradients, making it difficult to train the autoencoder. Regularization techniques, such as dropout and L1/L2 regularization, can help prevent overfitting.
Best practices
Best practices for using autoencoders include selecting the optimal number of layers and neurons, using regularization techniques to prevent overfitting, and monitoring the reconstruction error during training. It is also important to preprocess the data properly, including normalization and transformation.
The following table summarizes best practices for using autoencoders:
| Best Practice | Description |
|---|---|
| Select optimal number of layers and neurons | Avoid overfitting and vanishing gradients |
| Use regularization techniques | Prevent overfitting and improve generalization |
| Monitor reconstruction error | Ensure autoencoder is learning useful features |
| Preprocess data properly | Normalize and transform data for optimal performance |
Common misconceptions
One common misconception is that autoencoders are only useful for dimensionality reduction. However, autoencoders can also be used for feature extraction, anomaly detection, and generative modeling. Another misconception is that autoencoders are difficult to train, but with proper hyperparameter tuning and regularization, they can be trained effectively.
For example, autoencoders can be used to extract features from the Human Gene Expression dataset to identify potential biomarkers for disease diagnosis.
FAQ — 5 questions readers commonly ask, with detailed answers
Q1: What is the difference between an autoencoder and a PCA?
A1: An autoencoder is a neural network that can learn non-linear relationships between variables, while PCA is a linear dimensionality reduction technique.
Q2: How do I select the optimal number of layers and neurons for my autoencoder?
A2: The optimal number of layers and neurons depends on the complexity of the data and the task at hand. A good starting point is to use a small number of layers and neurons and increase them as needed.
Q3: Can I use autoencoders for regression tasks?
A3: Autoencoders are not suitable for regression tasks, as they are designed for dimensionality reduction and feature extraction. Instead, use a regression model such as a linear or logistic regression.
Q4: How do I avoid overfitting when training an autoencoder?
A4: Regularization techniques, such as dropout and L1/L2 regularization, can help prevent overfitting. Additionally, monitoring the reconstruction error during training can help identify overfitting.
Q5: Can I use autoencoders for generative modeling?
A5: Yes, autoencoders can be used for generative modeling by adding a generative component to the decoder. This allows the autoencoder to generate new samples that are similar to the training data.
Conclusion
In conclusion, autoencoders are a powerful tool for dimensionality reduction and feature extraction in drug discovery and development. By following best practices and avoiding common challenges, clinical pharmacists can use autoencoders to identify key features of drugs that contribute to their efficacy and safety. With the increasing availability of large public datasets, autoencoders have the potential to revolutionize the field of drug discovery and development.