Introduction — the problem in context
Case-control studies are a crucial aspect of pharmacoepidemiology, allowing researchers to investigate the relationship between drug exposures and adverse outcomes. However, these studies often rely on complex datasets, making it challenging to identify relevant features and draw meaningful conclusions. Machine learning techniques, particularly feature engineering, can help address these challenges.
A notable example of the importance of feature engineering in case-control studies is the investigation of the relationship between certain medications and the risk of developing a specific disease. By applying feature engineering techniques, researchers can identify the most relevant variables and interactions, ultimately leading to more accurate conclusions.
Background — setting, actors, constraints
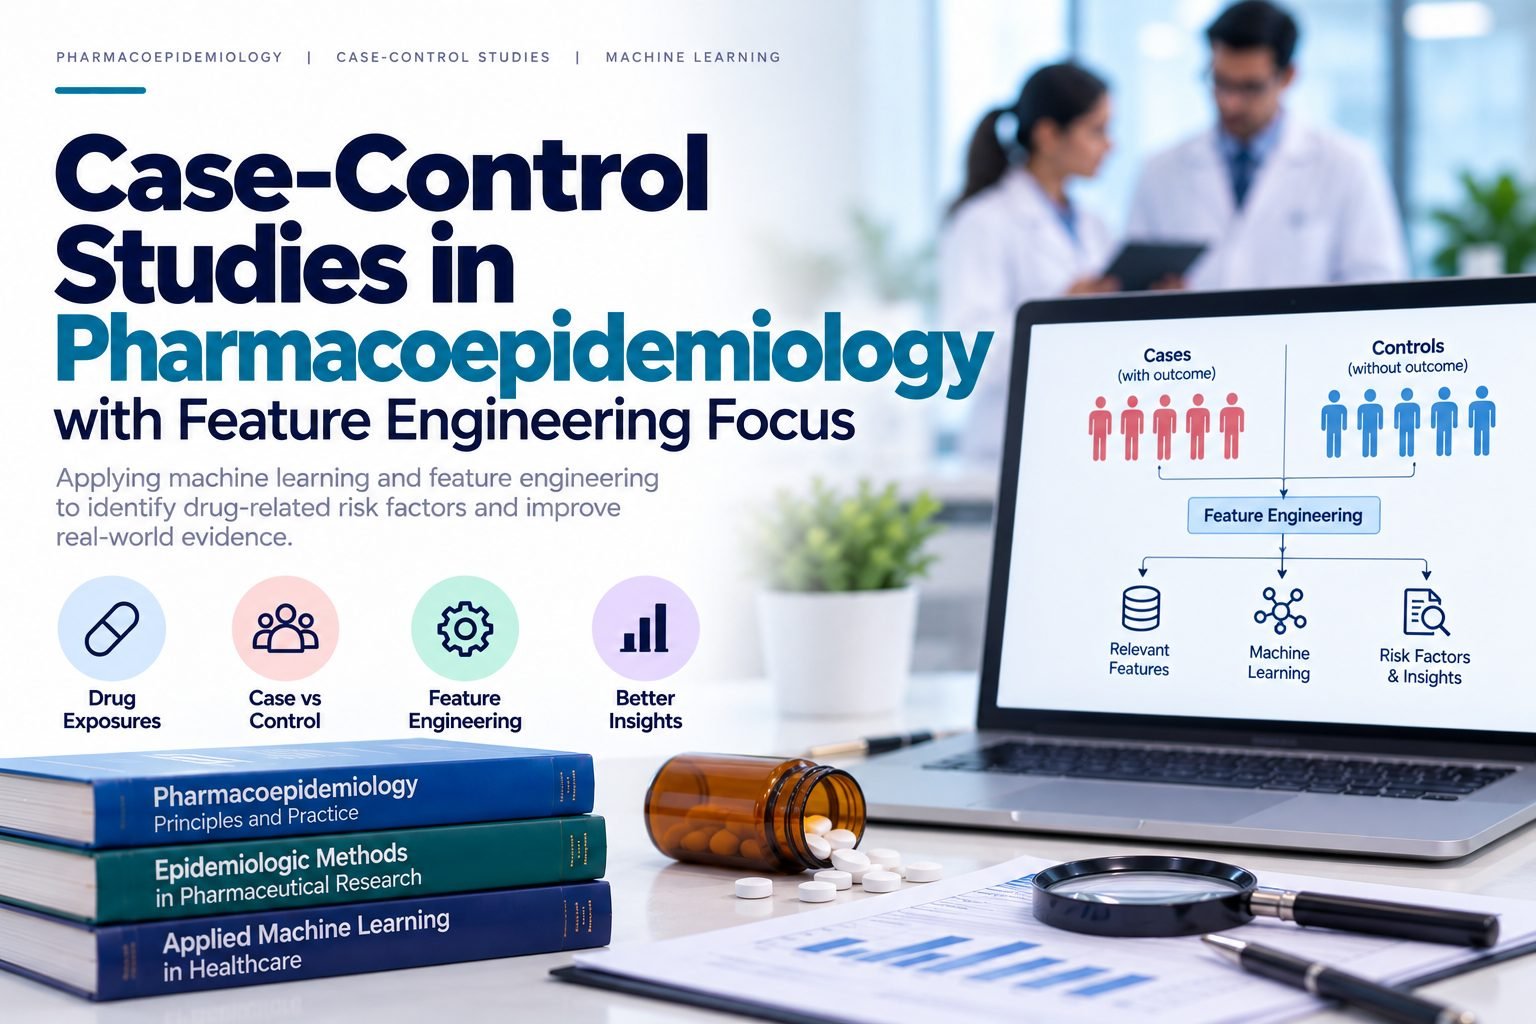
Pharmacoepidemiology is the study of the use and effects of drugs in large populations. Case-control studies are a key component of this field, involving the comparison of individuals with a specific outcome (cases) to those without the outcome (controls). The goal is to identify factors that contribute to the development of the outcome, including drug exposures.
Researchers in pharmacoepidemiology often face constraints such as limited data quality, incomplete information, and the need to account for various confounding variables. Feature engineering can help mitigate these issues by allowing researchers to select and transform the most relevant features, improving the accuracy and reliability of the results.
For instance, when investigating the relationship between a particular medication and the risk of a specific side effect, feature engineering can help identify the most important factors, such as dosage, duration of use, and patient demographics.
What was done — interventions and timeline
To apply feature engineering in case-control studies, researchers typically follow a series of steps. First, they collect and preprocess the data, handling missing values and performing data normalization. Next, they apply feature selection techniques, such as recursive feature elimination or correlation analysis, to identify the most relevant variables.
Once the relevant features are identified, researchers can apply feature transformation techniques, such as principal component analysis or feature scaling, to improve the model's performance. Finally, they train and evaluate machine learning models, using techniques such as cross-validation to ensure the results are reliable and generalizable.
A concrete example of this process is the use of feature engineering in a case-control study investigating the relationship between certain medications and the risk of developing a specific disease. By applying feature selection and transformation techniques, researchers can identify the most important factors contributing to the development of the disease.
Outcomes — measurable results
The application of feature engineering in case-control studies can lead to several measurable outcomes. First, it can improve the accuracy and reliability of the results, allowing researchers to draw more confident conclusions about the relationship between drug exposures and adverse outcomes.
Second, feature engineering can help reduce the dimensionality of the data, making it easier to interpret and visualize the results. Finally, it can facilitate the identification of novel risk factors and interactions, ultimately contributing to the development of more effective prevention and treatment strategies.
For example, a case-control study using feature engineering to investigate the relationship between certain medications and the risk of a specific side effect may find that a particular combination of factors, such as dosage and patient demographics, increases the risk of developing the side effect.
Lessons learned
Several lessons can be learned from the application of feature engineering in case-control studies. First, it is essential to carefully evaluate the quality and completeness of the data, as poor data quality can significantly impact the results.
Second, feature engineering requires a deep understanding of the underlying data and the research question, as well as expertise in machine learning and programming. Finally, it is crucial to validate the results using independent datasets and techniques, such as cross-validation, to ensure the findings are reliable and generalizable.
A notable example of the importance of data quality and validation is the investigation of the relationship between certain medications and the risk of developing a specific disease. By carefully evaluating the data and applying feature engineering techniques, researchers can identify the most relevant factors and draw more accurate conclusions.
How others can apply this
Researchers and practitioners in pharmacoepidemiology can apply feature engineering in case-control studies by following a series of steps. First, they should carefully evaluate the quality and completeness of the data, handling missing values and performing data normalization.
Next, they should apply feature selection techniques, such as recursive feature elimination or correlation analysis, to identify the most relevant variables. Once the relevant features are identified, they can apply feature transformation techniques, such as principal component analysis or feature scaling, to improve the model's performance.
Finally, they should train and evaluate machine learning models, using techniques such as cross-validation to ensure the results are reliable and generalizable. By following these steps and applying feature engineering techniques, researchers can improve the accuracy and reliability of their results, ultimately contributing to the development of more effective prevention and treatment strategies.
Conclusion
In conclusion, feature engineering is a powerful tool in case-control studies, allowing researchers to identify the most relevant features and draw more accurate conclusions about the relationship between drug exposures and adverse outcomes. By applying feature engineering techniques, researchers can improve the accuracy and reliability of their results, reduce the dimensionality of the data, and facilitate the identification of novel risk factors and interactions.
As the field of pharmacoepidemiology continues to evolve, the importance of feature engineering will only continue to grow. By embracing this technique and applying it in a rigorous and systematic manner, researchers can unlock new insights and contribute to the development of more effective prevention and treatment strategies.
A concrete example of the potential of feature engineering in case-control studies is the investigation of the relationship between certain medications and the risk of developing a specific disease. By carefully evaluating the data and applying feature engineering techniques, researchers can identify the most relevant factors and draw more accurate conclusions, ultimately leading to improved patient outcomes.