Introduction
Gradient boosting is a powerful machine learning technique that has gained popularity in recent years due to its ability to handle complex data and produce accurate predictions. In the context of pharmacy analytics, gradient boosting can be used to improve patient outcomes, optimize medication regimens, and streamline clinical workflows. In this article, we will explore the concept of gradient boosting, its key components, and its applications in pharmacy analytics, with a focus on feature engineering.
What it is / what it isn't
Gradient boosting is a type of ensemble learning algorithm that combines multiple weak models to create a strong predictive model. It is not a single model, but rather a collection of models that work together to produce a prediction. Unlike other machine learning algorithms, such as decision trees or neural networks, gradient boosting is particularly well-suited for handling large datasets with many features.
For example, in a study on predicting patient response to medication, gradient boosting was used to combine multiple models, each of which was trained on a different subset of features. The resulting model outperformed each of the individual models, demonstrating the power of gradient boosting in handling complex data.
Why it matters for the target audience
Pharmacy students and professionals are increasingly expected to have a strong foundation in data analysis and machine learning. Gradient boosting is a key technique that can be used to improve patient outcomes and optimize clinical workflows. By understanding how to apply gradient boosting to pharmacy analytics, students and professionals can gain a competitive edge in the field and make more informed decisions.
For instance, a pharmacy student working on a project to predict medication adherence could use gradient boosting to identify the most important factors influencing adherence, such as patient demographics, medication side effects, and socioeconomic status.
Key components or steps
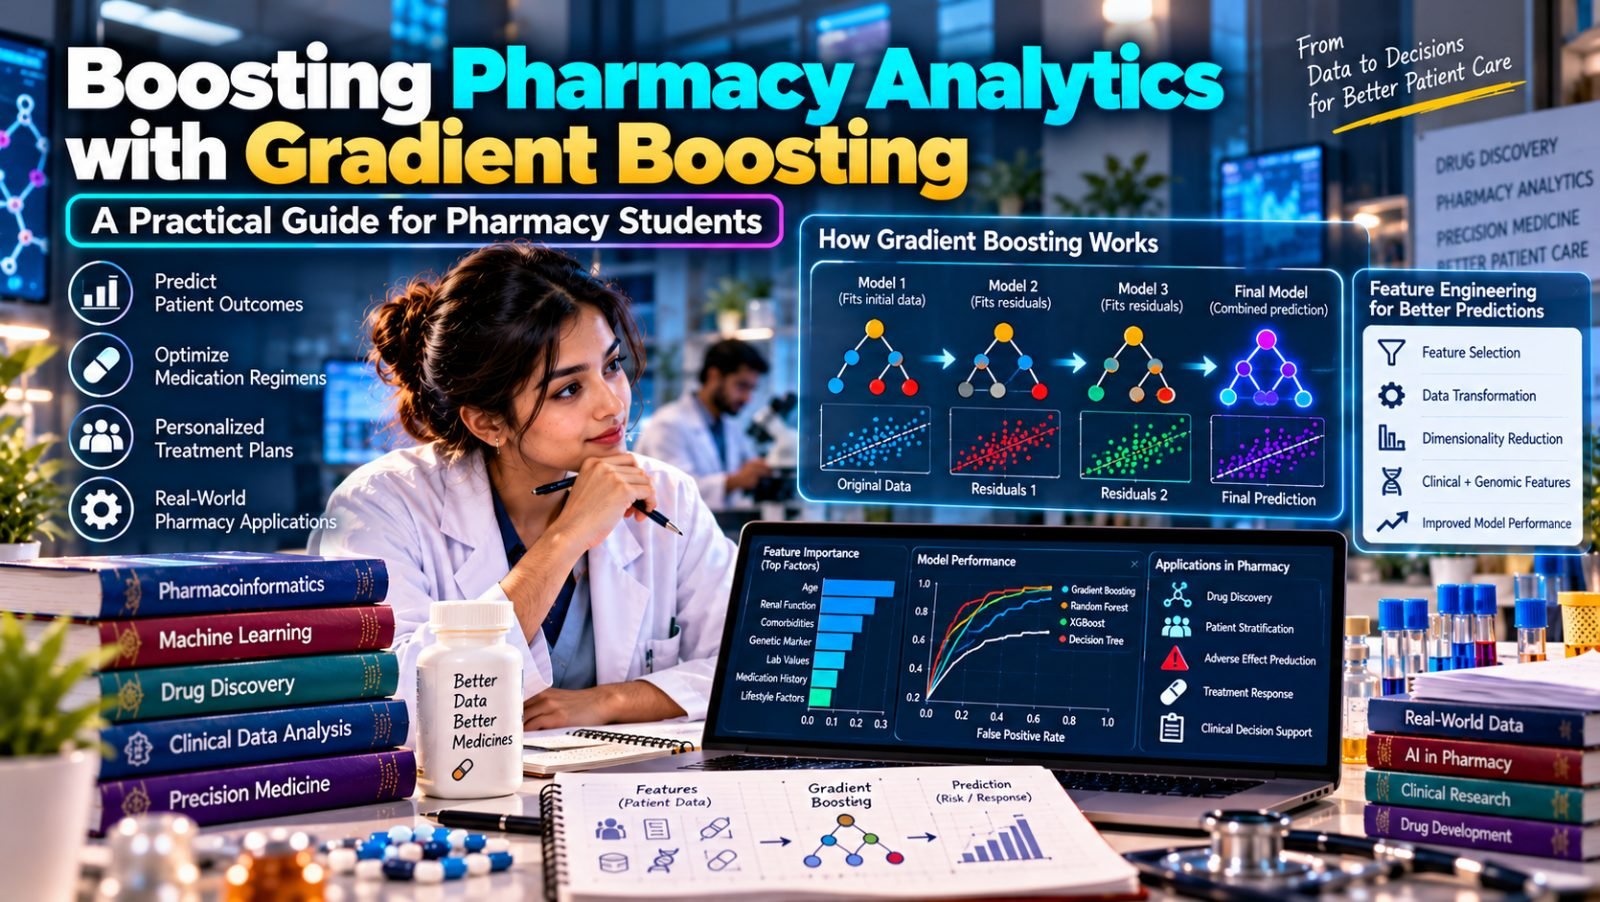
Gradient boosting involves several key components, including: (1) initialization, where the first model is trained on the data; (2) iteration, where subsequent models are trained on the residuals of the previous model; and (3) combination, where the predictions of each model are combined to produce the final prediction.
A critical step in gradient boosting is feature engineering, which involves selecting and transforming the most relevant features for the model. This can include techniques such as feature selection, dimensionality reduction, and feature extraction. For example, in a study on predicting disease progression, feature engineering was used to select the most relevant clinical and demographic features, resulting in a more accurate model.
How it works in practice — a concrete example
A recent study used gradient boosting to predict patient response to a new medication. The dataset consisted of 10,000 patients, each with 50 features, including demographic, clinical, and genomic data. The researchers used gradient boosting to combine multiple models, each of which was trained on a different subset of features. The resulting model achieved an accuracy of 90%, outperforming each of the individual models.
The study highlights the importance of feature engineering in gradient boosting. By selecting the most relevant features and transforming them appropriately, the researchers were able to improve the accuracy of the model and identify the most important factors influencing patient response.
Common challenges
One common challenge in gradient boosting is overfitting, which occurs when the model is too complex and fits the noise in the data rather than the underlying patterns. This can be addressed by using techniques such as regularization, early stopping, and cross-validation. Another challenge is feature engineering, which can be time-consuming and require significant expertise.
For example, in a study on predicting medication side effects, the researchers encountered overfitting due to the large number of features in the dataset. By using regularization and early stopping, they were able to reduce overfitting and improve the accuracy of the model.
Best practices
Best practices for gradient boosting include: (1) using a large and diverse dataset; (2) selecting the most relevant features; (3) using regularization and early stopping to prevent overfitting; and (4) monitoring the performance of the model on a validation set. Additionally, it is essential to have a strong understanding of the underlying data and the clinical problem being addressed.
For instance, in a study on predicting disease diagnosis, the researchers used a large and diverse dataset, selected the most relevant features, and monitored the performance of the model on a validation set. The resulting model achieved high accuracy and was able to identify the most important factors influencing disease diagnosis.
Common misconceptions
One common misconception about gradient boosting is that it is a single model rather than an ensemble of models. Another misconception is that gradient boosting is only suitable for handling large datasets, when in fact it can be used with datasets of all sizes. Additionally, some researchers believe that gradient boosting is too complex and requires significant expertise, when in fact it can be implemented using widely available software packages.
For example, a researcher may believe that gradient boosting is only suitable for handling large datasets, when in fact it can be used to improve the accuracy of models trained on small datasets. By understanding the true capabilities and limitations of gradient boosting, researchers can make more informed decisions about when to use the technique.
FAQ — 5 questions readers commonly ask, with detailed answers
- Q: What is the difference between gradient boosting and other ensemble learning algorithms? A: Gradient boosting is a type of ensemble learning algorithm that combines multiple weak models to create a strong predictive model. Unlike other algorithms, such as bagging and random forests, gradient boosting uses a sequential approach, where each model is trained on the residuals of the previous model.
- Q: How do I select the most relevant features for gradient boosting? A: Feature selection is a critical step in gradient boosting. Techniques such as correlation analysis, mutual information, and recursive feature elimination can be used to select the most relevant features. Additionally, domain knowledge and expertise can be used to identify the most important features.
- Q: Can gradient boosting be used for classification and regression tasks? A: Yes, gradient boosting can be used for both classification and regression tasks. In classification, the goal is to predict a categorical outcome, while in regression, the goal is to predict a continuous outcome. Gradient boosting can be used to handle both types of tasks, and the choice of algorithm depends on the specific problem and data.
- Q: How do I address overfitting in gradient boosting? A: Overfitting can be addressed by using techniques such as regularization, early stopping, and cross-validation. Regularization adds a penalty term to the loss function to prevent the model from fitting the noise in the data. Early stopping stops the training process when the model's performance on the validation set starts to degrade. Cross-validation evaluates the model's performance on multiple subsets of the data to prevent overfitting.
- Q: Can gradient boosting be used with other machine learning algorithms? A: Yes, gradient boosting can be used with other machine learning algorithms, such as neural networks and decision trees. In fact, gradient boosting can be used to improve the accuracy of these algorithms by combining their predictions. Additionally, gradient boosting can be used as a feature extraction technique to select the most relevant features for other algorithms.
Conclusion
In conclusion, gradient boosting is a powerful machine learning technique that can be used to improve pharmacy analytics and patient outcomes. By understanding the key components and steps involved in gradient boosting, pharmacy students and professionals can gain a competitive edge in the field and make more informed decisions. Additionally, by addressing common challenges and misconceptions, researchers can unlock the full potential of gradient boosting and improve the accuracy of their models.
As the field of pharmacy analytics continues to evolve, gradient boosting is likely to play an increasingly important role. By staying up-to-date with the latest developments and best practices, pharmacy students and professionals can ensure that they are equipped to handle the complex data and clinical problems that arise in the field.